CYRENYX™

CYRENYX™ · Life Sciences data & AI

Data stays where it lives. Knowledge gets connected.

CYRENYX builds governed layers of knowledge above your existing Life Sciences data estate, connecting clinical, imaging, RWE, omics, research, manufacturing and regulatory environments.

No data migration. No platform replacement.

The CYRENYX knowledge stack Seven data domains (clinical, imaging, RWE, omics, research, manufacturing, regulatory) stay on the ground floor, where they already live. Above them CYRENYX adds four governed layers: discover and catalogue; context; trust; govern. The top deck gives people, applications and AI agents AI-ready, governed access. People Applications AI agents AI-ready, governed access people · applications · AI agents Govern policy · purpose · consent · audit Trust lineage · quality · versions Context study · protocol · ontology Discover & catalogue metadata · profiles · owners Your data estate · stays in place 7 domains, in their own systems and regions
  • Clinical
  • Imaging
  • RWE
  • Omics
  • Research
  • Manufacturing
  • Regulatory
Your data stays on the ground floor. CYRENYX builds the layers of knowledge above it, so people, applications and AI agents get AI-ready, governed access.

One intelligence layer

It continuously integrates data, metadata, scientific context, lineage, quality and policy across distributed systems, while preserving domain ownership, source-of-truth integrity and data residency.

Governance in every layer

GxP-aligned controls, auditability, lineage, purpose-of-use, privacy and region-specific data requirements apply as data is discovered, accessed and used.

AI-ready, where it belongs

A connected, context-aware, AI-ready data estate: data stays in the systems and regions where it belongs, and becomes discoverable, interoperable, governed and usable across the enterprise.

The problem

Life Sciences data is everywhere. Its context isn't.

Clinical, imaging, real-world, omics, research and regulatory data sit in different systems, owned by different teams. Simple questions about it are still hard to answer:

  • Where is the authoritative dataset?
  • What does this dataset actually represent?
  • Which study, patient population or experiment is it associated with?
  • How was it transformed?
  • Does it contain sensitive information?
  • Can it be reused for this purpose?
  • Is it ready for AI?
  • Which models, analyses or downstream artifacts depend on it?

How CYRENYX works

From distributed data to trusted scientific intelligence

Five steps run continuously above the platforms you already have. Nothing is migrated: CYRENYX keeps governed references, metadata, relationships and context, and preserves them as data moves across the organisation.

Your data, where it lives Clinical · Imaging · RWE · Omics · Research · Manufacturing · Regulatory on AWS, Azure, Google Cloud, Databricks, Snowflake and your source systems
  1. DiscoverFinds data across distributed systems and catalogues its technical and scientific metadata.
  2. ContextualiseLinks it to studies, protocols, ontology and business meaning, and traces its lineage.
  3. GovernApplies access, privacy, consent and purpose-of-use controls, with a full audit trail.
  4. AssessScores quality, flags data issues and evaluates readiness for each AI use case.
  5. UseOpens governed access for people, applications and AI agents.
Built into every stepPurpose-of-use & access policy GxP-aligned audit trailLineage & versionsData residency
The outcome Data your teams can find, trust, reuse and safely put to work with AI

What makes CYRENYX different

A different starting point, not another platform

CYRENYX doesn't replace your data platforms, catalogue tools, agent frameworks or security products. It adds the governed scientific context that connects them. The difference is where it starts.

Where many programmes startWhere CYRENYX starts

Move the data into a new platform, then govern it

Leave the data where it is. Governed references, metadata and context across the systems and regions you already run.

Catalogue technical metadata

Add scientific context. Study, protocol, population and ontology beside the technical metadata.

Document access policies beside the data

Decide every query by policy. Purpose-of-use, consent and access apply to people and AI agents alike.

Start AI with a single model

Start AI with governed context. Specialist agents, each on a model suited to its work, on data assessed for that use.

Observe which model answered

Trace the whole path. From source data, through context, policy and validation, to the AI output.

Data+Scientific context+Governance+AI readiness+Specialist agents

One intelligence layer, built for Life Sciences, above the platforms you already trust.

Inside CYRENYX

What it looks like in use

Screens from the product demos, on synthetic data.
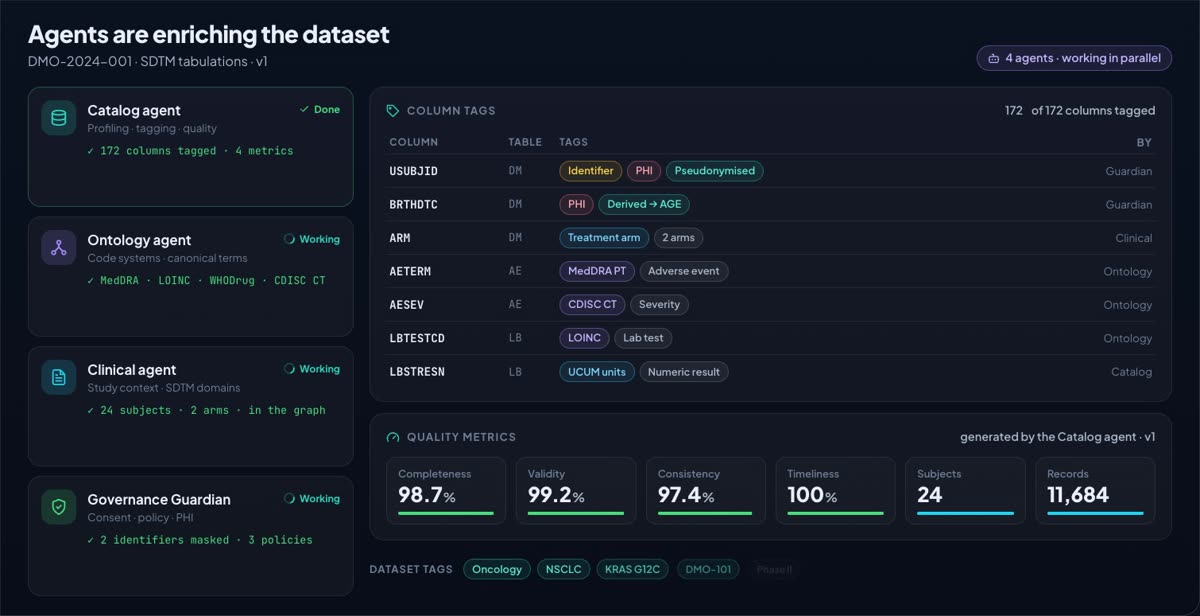
CYRENYX screen: Agents catalogue a new delivery where it lands: every column tagged, quality scored.
DiscoverAgents catalogue a new delivery where it lands: every column tagged, quality scored.
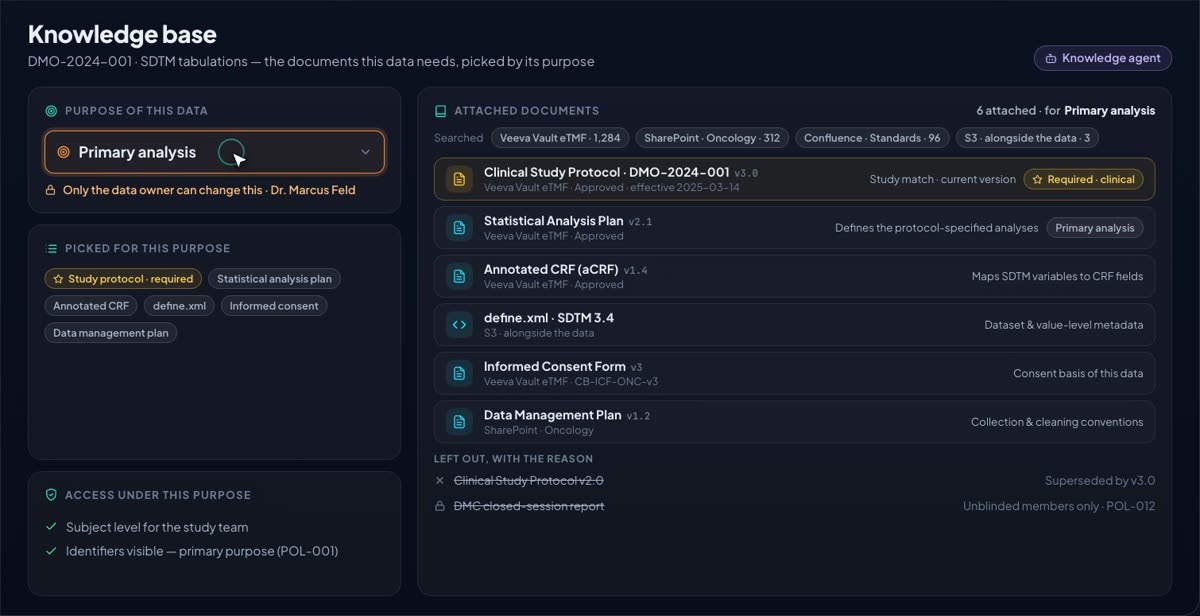
CYRENYX screen: The documents a dataset needs, picked by its purpose, and what's left out, with the reason.
ContextualiseThe documents a dataset needs, picked by its purpose, and what's left out, with the reason.
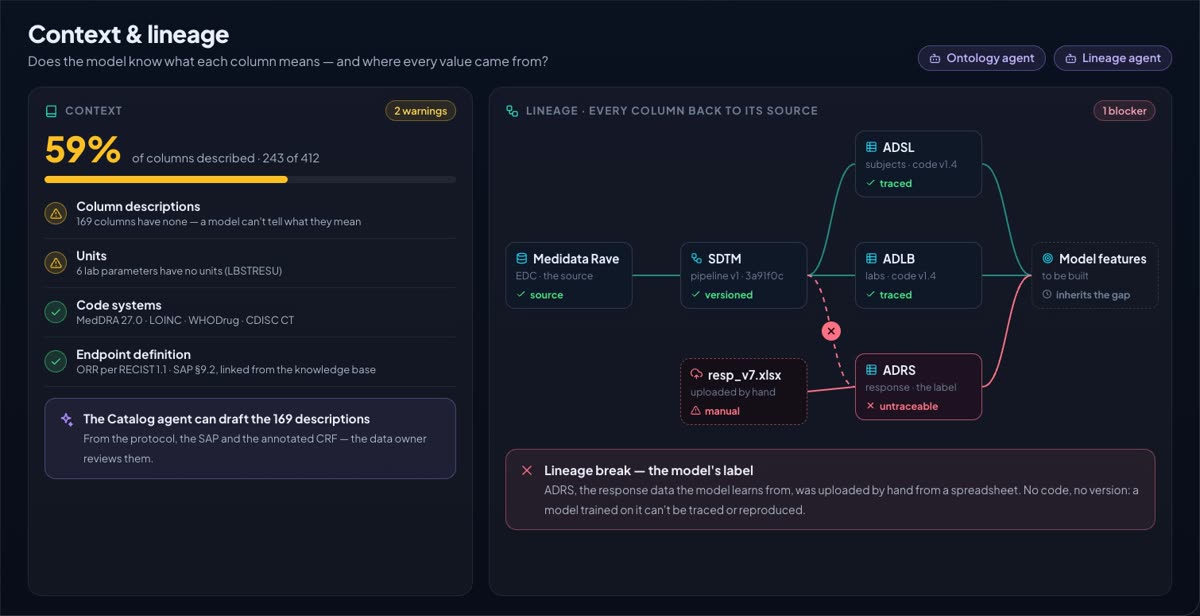
CYRENYX screen: Every column back to its source, including the break nobody knew about.
TraceEvery column back to its source, including the break nobody knew about.
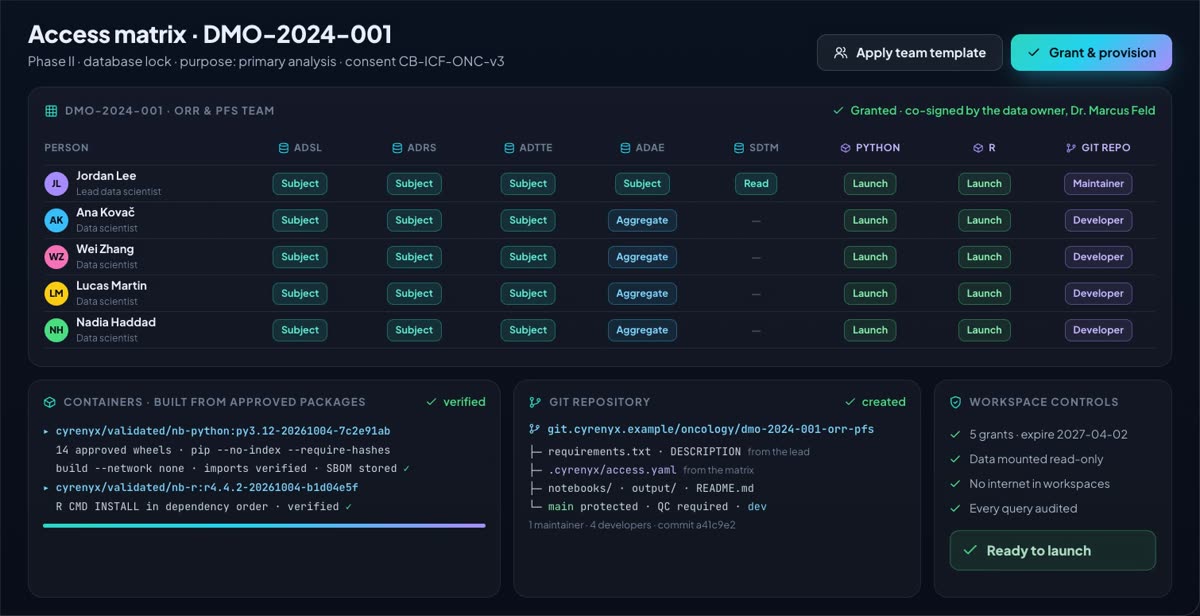
CYRENYX screen: The data owner grants access from the matrix; containers and Git are built from it.
GovernThe data owner grants access from the matrix; containers and Git are built from it.
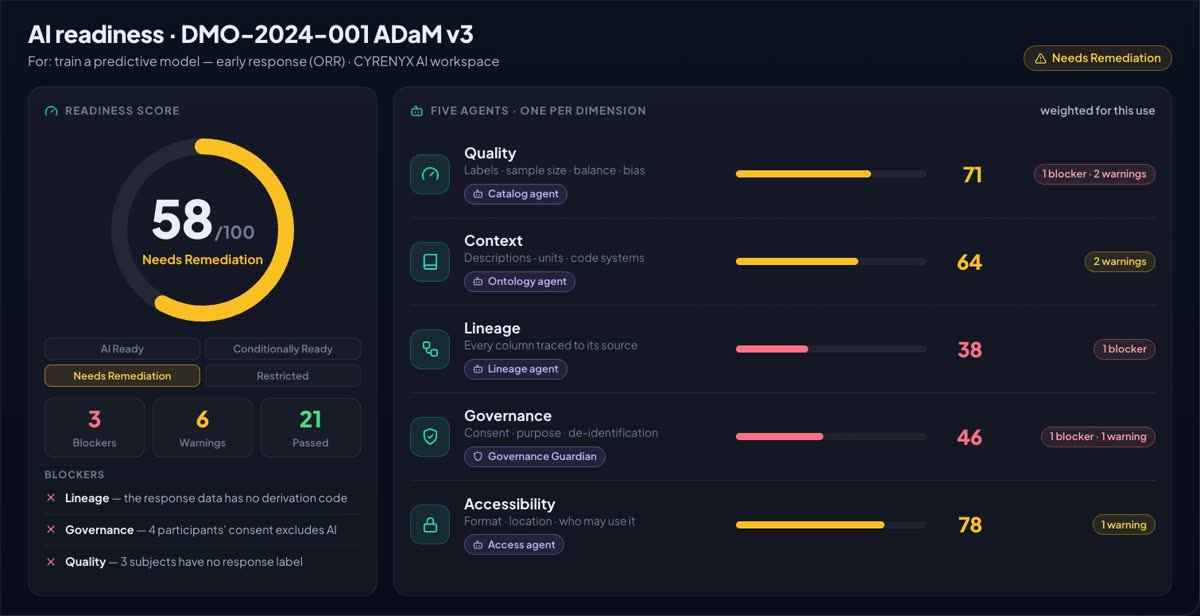
CYRENYX screen: AI readiness for a specific use, scored by specialist agents.
AssessAI readiness for a specific use, scored by specialist agents.
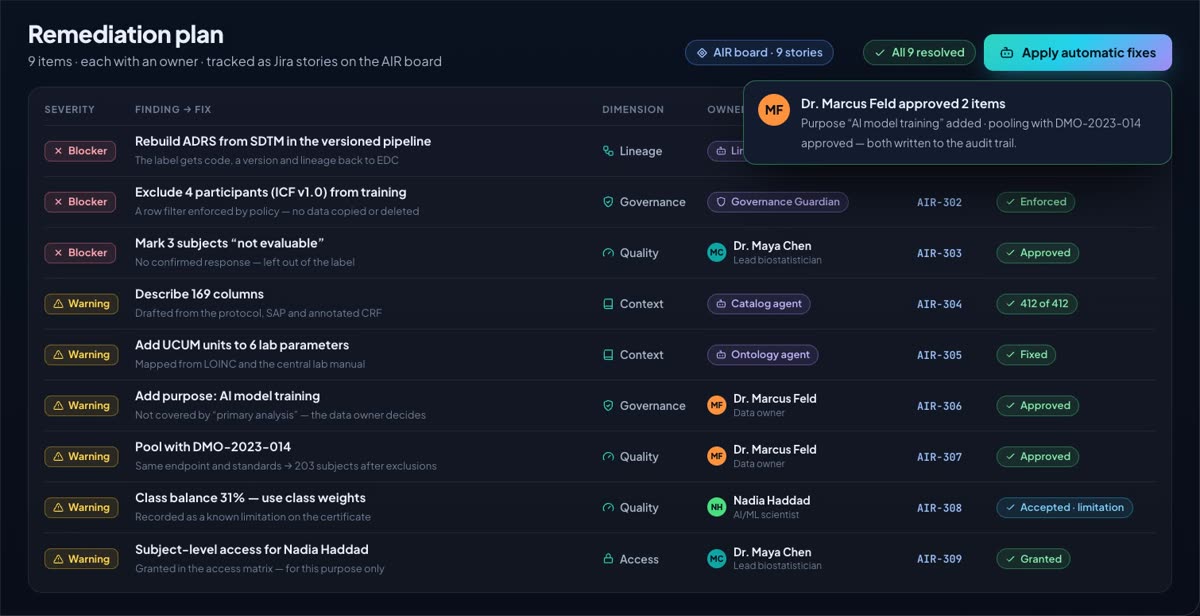
CYRENYX screen: Each finding becomes a fix with an owner, an agent or a person, and a Jira story.
ActEach finding becomes a fix with an owner, an agent or a person, and a Jira story.

What CYRENYX does

Eight services, and what each one delivers

Each service runs continuously across the systems you already run, not as a one-off documentation project.

ServiceWhat CYRENYX doesOutcome for your teams

Discover

Data discovery

Discovers data assets across clouds, lakehouses, clinical, imaging, research and document systems, in place.

One inventory of every dataset, with the authoritative copy identified.

Discover

Cataloguing

Catalogues technical and scientific metadata: schemas, profiles, owners, studies, endpoints and terms.

People search by what data means, not by where it is stored.

Contextualise

Scientific context

Contextualises data with its study, protocol, patient population, ontology and business meaning.

Anyone can tell what a dataset represents without tracking down the person who built it.

Contextualise

Lineage

Tracks lineage from source, through every transformation, to the analyses, models and submissions that use it.

Changes are made knowing what depends on them, and results can be reproduced.

Govern

Governance

Applies access, privacy, consent and purpose-of-use controls to every query, by people and agents alike.

The right access for the declared purpose, provable from a tamper-evident audit trail.

Assess

Data quality

Assesses quality continuously and identifies data issues as data arrives and changes.

Issues are caught before analysis, submission or model training, not after.

Assess

AI readiness

Evaluates whether data can safely and effectively support each AI use case, and what must be remediated.

Teams know which data is AI Ready, and exactly what to fix when it isn't.

Use

Governed access

Exposes approved data and context to people, applications and AI agents through governed interfaces.

One governed way in for every consumer, so teams reuse data instead of rebuilding it.

The outcome of using CYRENYX

A persistent intelligence layer, and what it changes

Context is no longer lost each time data moves between systems and teams.

Speed

Find the right data, fast

Teams locate the authoritative dataset and understand it without a hunt through systems and inboxes.

Reuse

Reuse instead of rebuild

Existing datasets are found and trusted, so work starts from what already exists.

Compliance

Governed by design

Purpose, consent and access rules are enforced on every query, and every step is auditable.

AI

AI on the right data

AI use cases start from data that has been assessed, documented and certified for that use.

Trust

Context that travels

Study, protocol, quality and lineage context stays with the data wherever it is used next.

Adoption

Value without migration

Start with one domain, workflow or use case on the platforms you run today, and expand from there.

See CYRENYX working

Short demos, on synthetic data

Each demo is captioned on screen, with no sound. Every study, patient and record in them is synthetic.

Demo 01 · 90 seconds

Intelligent Data Discovery

Connect CYRENYX to where a study delivery already lands and watch it identify the data assets, metadata and scientific context: the study, all 172 columns tagged, quality scored and the protocol attached. The pipeline it writes runs on the Airflow you already have.

Demo 02 · preview chapter

Scientific Context and Lineage

See how CYRENYX connects a dataset to its study, protocol and ontology, and traces every column from the EDC through each transformation to the features built on it, including the spreadsheet someone uploaded by hand.

Plays the context & lineage chapter of Demo 03. Ask for the full walkthrough.

Demo 03 · 90 seconds

AI Readiness

Evaluate whether data is suitable for AI. CYRENYX assesses quality, context, lineage, governance and accessibility and highlights what must be remediated before AI can safely use it. Watch a dataset move from Needs Remediation to AI Ready for its intended use.

Live walkthrough

Ask in plain language across clinical, imaging, RWE and omics data, and watch the same policy decide what a person, an application or an AI agent may see.

Demo 04 · live

Governed Search and AI Access

Search across distributed scientific data and expose approved context to applications and AI agents through governed interfaces.

Also · 90 seconds

From a new project to a validated analysis

Governed access for people, end to end. A data manager opens a study project and locks its purpose. Its lead data scientist sets the team's Python and R packages; a missing one is scanned on arrival and validated through a tracked workflow, with a Jira story for every step. Access comes from the access matrix, the containers and Git repository are built, and the team writes its first analysis.

AI readiness

AI readiness is a key part of the platform

Giving an AI model access to enterprise data is easy. Giving it access to the right data, with the right context, quality, lineage and governance is much harder. CYRENYX evaluates whether data is ready to support AI, for the use you intend rather than in the abstract.

Quality
  • Data quality
Context
  • Metadata completeness
  • Scientific context
  • Ontology and semantic mapping
Lineage
  • Lineage
  • Version and freshness
Governance
  • PHI / PII sensitivity
  • Access policy
  • Purpose-of-use
Accessibility
  • Machine accessibility

A clear view of every dataset, for every use

  • AI ReadyPasses every check for the declared use, and carries a readiness certificate.
  • Conditionally ReadyUsable for the declared use under recorded conditions, such as a known limitation or a restricted workspace.
  • Needs RemediationBlockers to fix first, each with an owner and a tracked fix; agents handle many of them.
  • RestrictedPolicy, consent or sensitivity rules this use out until governance decides otherwise.

AI readiness becomes one measurable outcome of the broader CYRENYX intelligence layer, re-checked at every new data cut. Watch Demo 03.

Governed AI agents

Build AI agents on the same governed context as your data

Most enterprise agent frameworks start with the model and then connect it to tools and data. CYRENYX starts with the governed data context. Because it already connects data, metadata, lineage, ontology, quality, ownership, access policy and purpose-of-use across your estate, agents are built with that context from the beginning.

The agent is not another intelligence layer disconnected from enterprise governance. It operates within the same intelligence layer that understands the data.

A team of specialists, not a single model

Work is planned by a Conductor and delegated to specialist agents. Each one sees only the tools and data its role allows, and can run on the model that suits its work: a general-purpose language model, a domain model, or a validated in-house model with its own model card.

A question or a workflow step“Which DMO-2024-001 subjects had grade 3 pneumonitis, and is that data ready for the safety model?”
ConductorPlans the work and delegates it. Holds no data tools of its own.
  • Clinical DataStudy data · SDTM and ADaMe.g. a general-purpose LLM
  • ImagingDICOM series · reads · endpointse.g. an imaging model
  • Real-world evidenceClaims · EHR · registriese.g. a general-purpose LLM
  • Ontology & SemanticMedDRA · LOINC · CDISC termse.g. a terminology model
  • Catalog & LineageMetadata · lineage · qualitye.g. a small, fast model
  • Therapeutic areaEndpoints · standards · landscapee.g. a validated in-house model
Governance GuardianReviews every answer against policy, consent and purpose before it's released.
Answer or artifactCited to its datasets and studies · every step in the audit trail

From governed data to governed agents

Create and deploy specialised agents for clinical, imaging, RWE, omics, research, regulatory and enterprise workflows, each configured around:

  1. PurposeWhat the agent is intended to do
  2. DataWhich governed data it can access
  3. ToolsWhich APIs and actions it can use
  4. ModelWhich approved model, or models, suit each workload
  5. IdentityHow the agent is identified and authorised
  6. PolicyWhich enterprise controls apply
  7. ValidationWhat checks occur during the workflow
  8. Human oversightWhere review or approval is required

Introduce agentic workflows without creating a separate security and governance architecture around every agent.

Security follows the agent

Inside your security architecture

CYRENYX works within your existing security architecture rather than replacing it. Agents operate within your:

  • Identity and access controls
  • Role-based permissions
  • Network boundaries and private endpoints
  • Secrets management
  • Encryption controls
  • Data-residency requirements
  • API security
  • Logging and monitoring
  • Approved model policies
  • Regional and organisational data restrictions

Your security controls remain the authority. CYRENYX adds the context, such as ownership, sensitivity and purpose-of-use, to help apply them to AI workflows.

Automated checks

Verification through the lifecycle

Reliability shouldn't depend on trusting a single model response. Depending on the use case, checks include:

  • Schema and required-field validation
  • Data-quality rules
  • Policy and permission checks
  • Tool-access checks
  • Expected-output validation
  • Scientific or business rules
  • Source and citation verification
  • Confidence thresholds

When a check falls short, the workflow retries, stops, escalates or asks for human review. The aim isn't to claim an agent always knows it's right; it's to make verification a deliberate part of the workflow.

Monitoring

Visibility after deployment

Agent behaviour changes as models, prompts, tools, data and workflows evolve. Teams can monitor:

  • Agent activity and workflow execution
  • Models used and tools invoked
  • Data accessed
  • Validation results
  • Errors and exceptions
  • Latency, resource and model consumption
  • Policy events
  • Human interventions

An operational record of how agents behave, and which workflows need investigation or improvement.

Traceability

Trace the path from data to AI output

Traditional observability may tell you which model produced a response. CYRENYX connects the broader chain of context, so AI activity can be traced back to the governed data and context that supported it.

  1. Source data
  2. Dataset & version
  3. Scientific context
  4. Policy & purpose
  5. Agent
  6. Model
  7. Tools
  8. Validation
  9. Human review
  10. Output / artifact

In regulated environments, this record can contribute to the evidence and audit trail that your established validation and quality processes require.

Deploy where the data already lives

Agent workloads and sensitive scientific data don't move to a separate CYRENYX-hosted platform. Depending on your architecture, agents and models run within your existing cloud, Kubernetes or private environments.

Work with the architecture you already trust.

Use the models and tools you approve

  • Enterprise-approved models
  • Cloud-hosted models
  • Customer-hosted models
  • Open-source models
  • Domain-specific models
  • Existing APIs and tools

A different starting point for enterprise agents

CYRENYX isn't trying to replace every agent-development framework, orchestration platform or security product. Its differentiation is the context underneath the agent.

The same intelligence layer that helps your organisation understand its data answers the questions every agent needs answered first:

  • What is this data?
  • Where did it come from?
  • Can it be trusted?
  • Who can use it?
  • For what purpose?

Works with what you run

One layer above the platforms you already use

The existing platforms continue to store, process and execute. CYRENYX adds the context, governance and intelligence layer above them.

People, applications & AI agents
ResearchersData stewardsStudy teamsApplicationsAI agentsRegulatory & audit
CYRENYXdiscover · catalogue · contextualise · lineage · quality · governance · AI readiness · governed access
Cloud-native servicesDatabricksSnowflakeAirflowMLflowClinical systemsImaging systemsRWE platformsOmics environmentsAPIs & enterprise services
Your platforms · they keep storing, processing and executing

No migration required

Start with one use case. Expand from there.

CYRENYX does not require you to move your data into another proprietary platform. It maintains governed references, metadata, relationships and context across the systems you already have.

So instead of another migration programme, teams begin with one domain, one workflow or one use case, and expand incrementally.

Your data stays in

  • AWS
  • Azure
  • Google Cloud
  • Databricks
  • Snowflake
  • Clinical systems
  • Imaging repositories
  • Research platforms
  • Document systems

Governance

Every query is decided by policy

The same policy engine decides what each person, application and agent sees, as full access, masked, aggregate-only or metadata-only, for the purpose they declared.

Purpose of use

Every session declares a purpose. Change the purpose, and access changes with it, live.

Consent & reuse

Consent bases and reuse restrictions travel with the data, and small cells are suppressed in aggregates.

Tamper-evident audit

Every query, tool call and agent step is written to a hash-chained audit trail that can be verified at any time.

Secrets by reference

Credentials never land in the catalogue, the logs or the audit trail, and agents can read but never change data.

Live demo

Try it on synthetic data

The live demo runs Demo Pharma, a fictional sponsor with oncology, immunology and neuroscience studies. Sign in as a scientist, a data owner or a steward and watch access change with the role and the purpose.

Sponsor
Demo Pharma (fictional)
Studies
DMO-2023-014, DMO-2024-001 and more
Data
Clinical, imaging, omics, registry and documents, all synthetic
Access
By invitation; personas from scientist to data owner

Customisable

Fitted to your architecture, not the other way round

No two Life Sciences landscapes look alike. Every CYRENYX deployment is customised to the client's own architecture: where it runs, what it connects to, who signs in and which rules apply. See the reference architectures.

Deployment

Runs where you choose

In your own AWS, Azure or Google Cloud account, or on your Kubernetes cluster, set up with infrastructure as code.

Integration

Connects to your platforms

Over 25 ready connectors, from Veeva Vault, Medidata Rave and SharePoint to DICOMweb, FHIR and S3, plus new ones for your own systems.

Identity

Your sign-in

Single sign-on with Microsoft Entra ID, AD FS, Okta or any SAML 2.0 provider, with your groups mapped to roles.

Governance

Your rules

Purposes of use, access policies, consent bases and approval workflows modelled on how your organisation already works.

Organisation

Your structure

Affiliates, CROs and partners as separate tenants, each with its own data residency, encryption keys and licensed modules.

Context & AI

Your ontology and models

Extend the ontology with your own entities and terms, and use Claude through your own account or run without an external model.

Reference architectures

CYRENYX inside your cloud: AWS, Azure or Google Cloud

The same landing zone on every cloud, built as code in your own organisation: a private Kubernetes cluster in a private network, your keys, your logs, and your data platforms read where they are. Pick a cloud to see its services.

CYRENYX inside your Amazon Web Services landing zoneCYRENYX runs on a private EKS cluster in the production environment of your own Amazon Web Services organisation, signs people in with your identity provider, reads your data platforms in place and is delivered as code.Your peopleScientistsData stewardsData ownersStudy teamsand their AI agentsYour sign-inEntra ID · OktaAD FSany SAML 2.0HTTPS + single sign-onYOUR AWS ORGANIZATIONNetwork accountTransit Gateway hubsandbox never attachedSecurity & log archiveCloudTrail → locked bucketGuardDuty · Security HubData domains accountS3 domainsclinical · RWE · imagingGlue Data CatalogPROD ACCOUNT · ALSO SBX, DEV, TESTPrivate VPCPrivate EKS cluster · CYRENYX from the Helm chartStudio & APIweb app · REST · liveGoverned agentsMCP tools · read-onlyPolicy enginepurpose · consent · auditCatalogue & graphlineage · ontologyPipelinesAirflow in the clusterWorkbenchnotebooks · workspacesSearchOpenSearch ServiceKeysKMS, customer-managed keysImagesAmazon ECRBurst computeAWS BatchDelivered as code: Terraform landing zone + Helm chart through Argo CDReleases to test and prod need approval · the sandbox is an island, never peeredYour data platformsVeeva VaultMedidata RavePACS · DICOMwebLIMS · ELN · BenchlingSharePoint · BoxFHIR serversDNAnexus · Seven BridgesS3 · Blob · GCSread in place: metadata+ permitted samplesClaude (optional)your own account,or no external modelgoverned outputs
Swipe sideways to see the whole diagram. Amazon Web Services: CYRENYX in the production environment of your own organisation, next to separate network, security and data-domain accounts. Solid arrows: requests and metadata. Dashed: optional.
CYRENYX inside your Microsoft Azure landing zoneCYRENYX runs on a private AKS cluster in the production environment of your own Microsoft Azure organisation, signs people in with your identity provider, reads your data platforms in place and is delivered as code.Your peopleScientistsData stewardsData ownersStudy teamsand their AI agentsYour sign-inEntra ID · OktaAD FSany SAML 2.0HTTPS + single sign-onYOUR AZURE TENANT · MANAGEMENT GROUPSConnectivity subscriptionHub VNet · peeringsandbox never peeredSecurity subscriptionLog Analytics(Sentinel-ready)Defender for CloudData domains subscriptionADLS Gen2 domainsclinical · RWE · imagingMicrosoft PurviewPROD SUBSCRIPTION · ALSO SBX, DEV, TESTPrivate VNetPrivate AKS cluster · CYRENYX from the Helm chartStudio & APIweb app · REST · liveGoverned agentsMCP tools · read-onlyPolicy enginepurpose · consent · auditCatalogue & graphlineage · ontologyPipelinesAirflow in the clusterWorkbenchnotebooks · workspacesSearchAzure AI Searchor OpenSearchKeysKey Vault,purge protectionImagesContainer RegistryBurst computeAzure BatchDelivered as code: Terraform landing zone + Helm chart through Argo CDReleases to test and prod need approval · the sandbox is an island, never peeredYour data platformsVeeva VaultMedidata RavePACS · DICOMwebLIMS · ELN · BenchlingSharePoint · BoxFHIR serversDNAnexus · Seven BridgesS3 · Blob · GCSread in place: metadata+ permitted samplesClaude (optional)your own account,or no external modelgoverned outputs
Swipe sideways to see the whole diagram. Microsoft Azure: CYRENYX in the production environment of your own organisation, next to separate network, security and data-domain subscriptions. Solid arrows: requests and metadata. Dashed: optional.
CYRENYX inside your Google Cloud landing zoneCYRENYX runs on a private GKE cluster in the production environment of your own Google Cloud organisation, signs people in with your identity provider, reads your data platforms in place and is delivered as code.Your peopleScientistsData stewardsData ownersStudy teamsand their AI agentsYour sign-inEntra ID · OktaAD FSany SAML 2.0HTTPS + single sign-onYOUR GOOGLE CLOUD ORGANIZATIONNetwork host projectShared VPCsandbox never joinedSecurity projectCentral log bucket(CMEK)Cloud Audit LogsData domains projectGCS domains (CMEK)clinical · RWE · imagingDataplexPROD PROJECT · ALSO SBX, DEV, TESTPrivate VPC (Shared VPC)Private GKE cluster · CYRENYX from the Helm chartStudio & APIweb app · REST · liveGoverned agentsMCP tools · read-onlyPolicy enginepurpose · consent · auditCatalogue & graphlineage · ontologyPipelinesAirflow in the clusterWorkbenchnotebooks · workspacesSearchOpenSearch on GKEKeysCloud KMS (CMEK)ImagesArtifact RegistryBurst computeBatch APIDelivered as code: Terraform landing zone + Helm chart through Argo CDReleases to test and prod need approval · the sandbox is an island, never peeredYour data platformsVeeva VaultMedidata RavePACS · DICOMwebLIMS · ELN · BenchlingSharePoint · BoxFHIR serversDNAnexus · Seven BridgesS3 · Blob · GCSread in place: metadata+ permitted samplesClaude (optional)your own account,or no external modelgoverned outputs
Swipe sideways to see the whole diagram. Google Cloud: CYRENYX in the production environment of your own organisation, next to separate network, security and data-domain projects. Solid arrows: requests and metadata. Dashed: optional.

Across every cloud you use

Most Life Sciences companies run more than one cloud. CYRENYX runs in the one you choose and governs data that stays where it lives, wherever that is.

One governed layer across every cloudCYRENYX runs in the cloud you choose and governs data that stays where it lives on AWS, Azure, Google Cloud, on-premises and in SaaS systems, with a tenant per affiliate or partner.Your people and agentssingle sign-on: Entra ID · Okta · AD FS · SAML 2.0CYRENYX™one governed layercatalogue · graph · policy · agents · auditruns in the cloud you chooseAmazon Web ServicesS3 data lakes · Glue Data CatalogEKS workspaces · AWS BatchOpenSearch ServiceMicrosoft AzureADLS Gen2 · Blob · PurviewAKS workspaces · Azure BatchAzure AI SearchGoogle CloudGCS · DataplexGKE workspaces · Batch APIOpenSearch on GKEOn-premises and SaaSPACS · DICOMweb · LIMS · ELNVeeva Vault · Medidata RaveSharePoint · Box · DocumentumTenants per affiliate and partner: their own data residency, keys and modulesGlobal R&DUnited StatesEU affiliatedata stays in the EUJapan affiliatedata stays in JapanCRO partnerits own tenant and keys
Swipe sideways to see the whole diagram. Only metadata and the samples your policies permit reach CYRENYX; each affiliate or partner can be its own tenant with its own residency and keys.

CYRENYX

Keep the data where it is. Add the intelligence layer above it.

Discover. Contextualise. Govern. Assess. Use.

And know when your data is ready for AI. Talk to Astatine Data Services about a walkthrough for your team, or a pilot fitted to your own architecture.